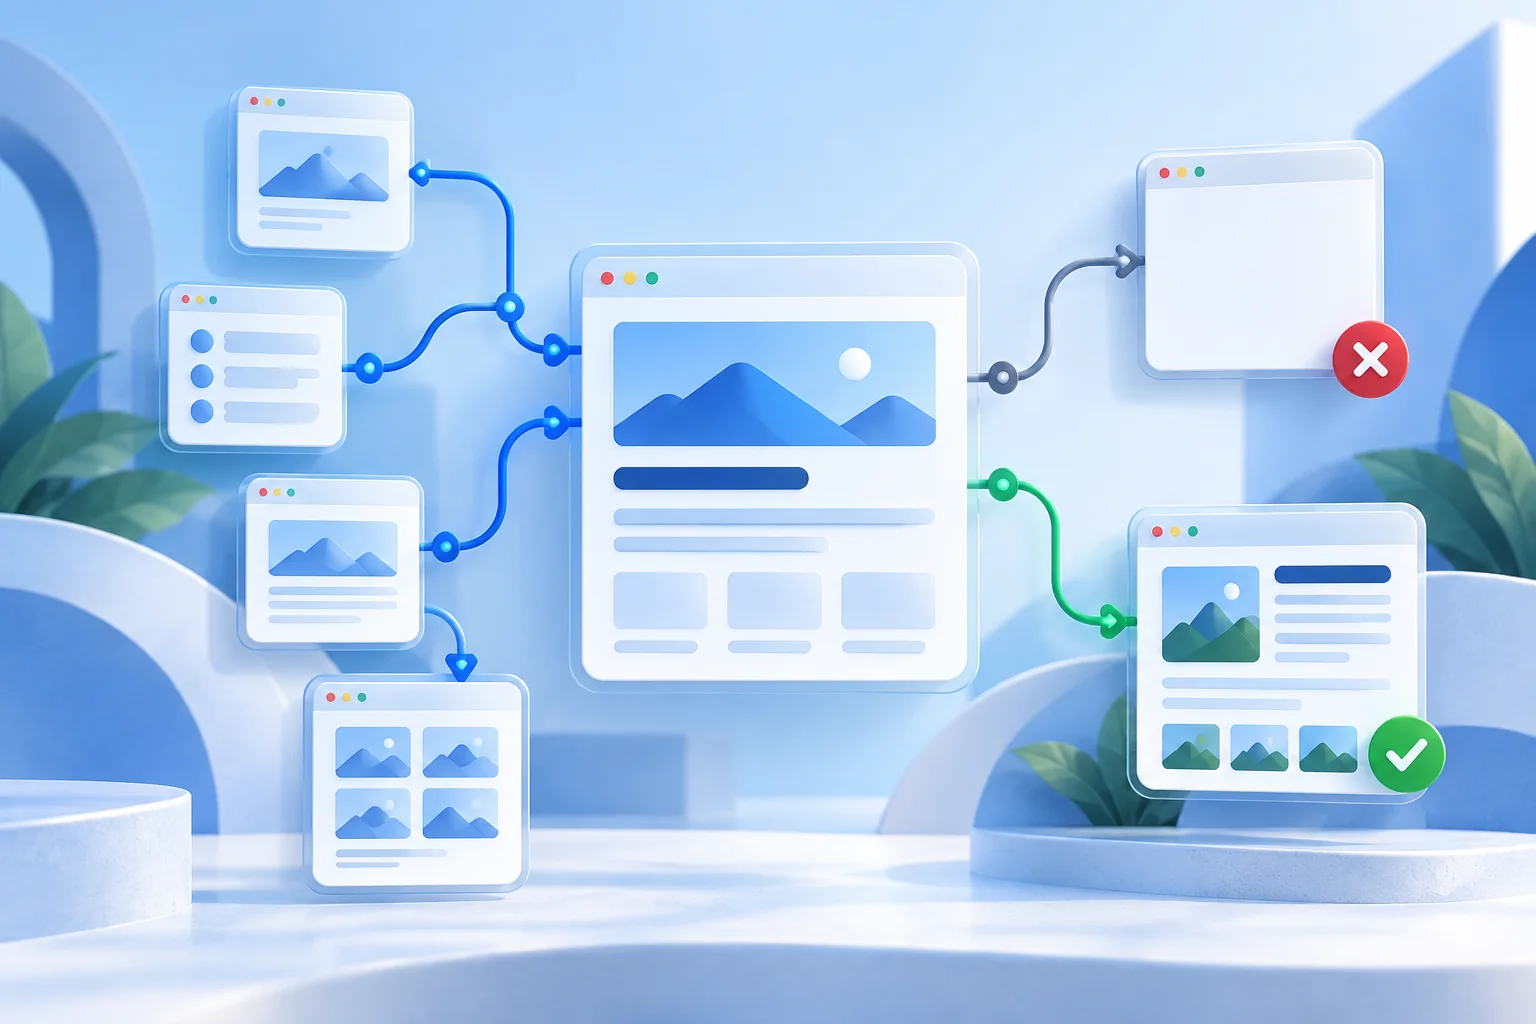
When a chatbot cannot answer a question that appears on your website, find the break in the chain: could it reach the page, extract useful text, save that source, and choose it for the answer? A normal-looking page in your own browser proves only the first part of the visitor experience.
Start with one exact question and the exact URL that should answer it. Inspect the assistant’s saved sources, open that URL in a private browser window, and compare the visible answer with what the assistant retrieved. This is faster than rewriting the prompt or uploading your entire website again.
First, identify which failure you have
| What you observe | Likely layer | First check |
|---|---|---|
| Setup reports that no useful content was found | Access or extraction | Open the same public URL without being signed in; check that the main text is present. |
| The assistant knows the homepage but not a service page | Discovery or crawl budget | Find the service URL in saved sources and add it explicitly if missing. |
| A source exists, but the answer is old | Freshness or conflicting pages | Compare the saved page with the current canonical page; refresh the source. |
| The page is present, but the reply is unrelated | Retrieval or answer selection | Ask a precise question and inspect the cited source and conversation. |
| A public answer works, but an order or account lookup fails | Authorization or connector | Check the approved connected service and visitor verification; public crawling cannot supply private records. |
1. Confirm the URL is public and actually contains the answer
Open the page in a private window with no account session. If it asks for a login, displays a challenge, redirects to an unrelated page, or requires a form submission, a public website crawl cannot treat it as ordinary business knowledge. Give the assistant an approved document or use a connector with the appropriate authorization instead.
Look beyond the title and meta description. The page needs readable body content that actually answers the customer’s question. A hero image saying “Everything you need” and a button to contact sales do not explain prices, service areas, eligibility, or policies. Publish those facts on an accessible page if customers need the assistant to answer them.
2. Check what the page exposes after it loads
Modern sites often render text after an API response, open a consent panel over the content, or place details inside tabs. Chirps uses a browser-based crawl, so JavaScript by itself is not a reason a page fails. Timing, access checks, and where the content appears can still affect what is extracted. Check the actual saved source rather than assuming every browser-rendered element was captured.
If a price table appears only after selecting a location, or a policy lives behind an authenticated account, make a stable public explanation page for the general answer. Google’s JavaScript SEO guidance is useful background on how rendered content differs from initial HTML; its Googlebot behavior should not be assumed to describe every chatbot crawler.
3. Inspect the source list, not just the final answer
In Chirps, review the source URLs and the page title or description saved during setup. If the required page is absent, add that exact URL through the knowledge workflow and run the relevant training or recrawl action. Check plan limits: page and depth allowances decide how far a discovery crawl can go. A deeply linked FAQ may never be reached within a small page budget even though the homepage loads perfectly.
If several URLs contain almost identical text, determine which one should be authoritative. The crawler can skip content that is effectively duplicate or too thin to be useful. A dozen copied location pages with a different heading are not a substitute for one clear service policy. For broader preparation, see the RAG guide for customer support.
4. Separate missing knowledge from wrong source choice
A chatbot can have a relevant page and still answer poorly if an outdated upload, an old policy page, or an unrelated search result wins retrieval. Ask the exact customer question and inspect the Sources shown with the reply. If the wrong page appears, fix the source set and its conflicting content first. If the right page appears but the answer is incomplete, make the key conditions explicit in the page itself.
Public website search can help with a public fact beyond the initial crawl when that capability is enabled and allowed by the assistant owner. It is not a substitute for verified order data, live inventory, a customer account, or a booking record. Those need the appropriate connected service and access checks. A useful assistant distinguishes missing public content from private data it is not authorized to reveal.
5. Refresh after the business changes
Training is a snapshot of the sources available at that time. After changing a service page, price, policy, or product category, refresh the relevant knowledge and repeat the same test question. If the page and answer still differ, inspect whether an older URL remains in the source set. The guide to fixing “I don't know” answers covers related response failures.
A ten-minute diagnostic you can repeat
- Write one real customer question and the URL that should answer it.
- Open the URL in a private window and check the actual body text, not only its metadata.
- Confirm the page is in the assistant’s saved sources; add the exact URL if it is missing.
- Compare the saved title and content with the live page; remove or refresh stale copies.
- Ask the question in the live widget and inspect the answer’s Sources.
- Try one paraphrase and one follow-up to see whether the assistant keeps the right context.
- If the answer depends on a private or changing record, test the authorized connector separately.
When the website has almost no content
A one-screen site may have a valid URL, logo, and working buttons but still contain too little business information to train a useful assistant. That is an information gap, not a reason to trap the owner in a retry loop. Add the business name, services, audience, common questions, and contact route manually; then attach richer pages or documents as they become available. Chirps supports manual setup when website discovery cannot supply enough information.
What a good result looks like
The assistant should answer the customer’s question in plain language, point to the relevant source or next step, and say when a detail is not verified. Its source list should contain the page you would trust a new employee to read. If that page does not exist yet, creating it is usually the durable fix—for your visitors and your assistant.